We will remember the week of 10 to 16 March 2026 as the week of the humanoids: a giant training hall in Munich, an NVIDIA keynote at GTC, a Chinese five-year plan, a puppet robot on stage, and a projection of three billion machines by 2060. Six announcements, six headliners, and the temptation to sort them into camps — Europe against China, open source against proprietary. This misses the only sentence that links them, and it is NEURA Robotics that wrote it in black and white: the main bottleneck in robotics is no longer hardware, it is the acquisition of large quantities of real physical learning data.
Once this sentence is established, the week ceases to be a juxtaposition. It becomes a battle — with three incompatible answers — around a single question: where does the data that trains robots come from? Picking it up by hand, synthesising it through computation, or decreeing it by the State. No one has won. We fought to find out who holds the factory.
Answer No. 1: Picking it up by hand
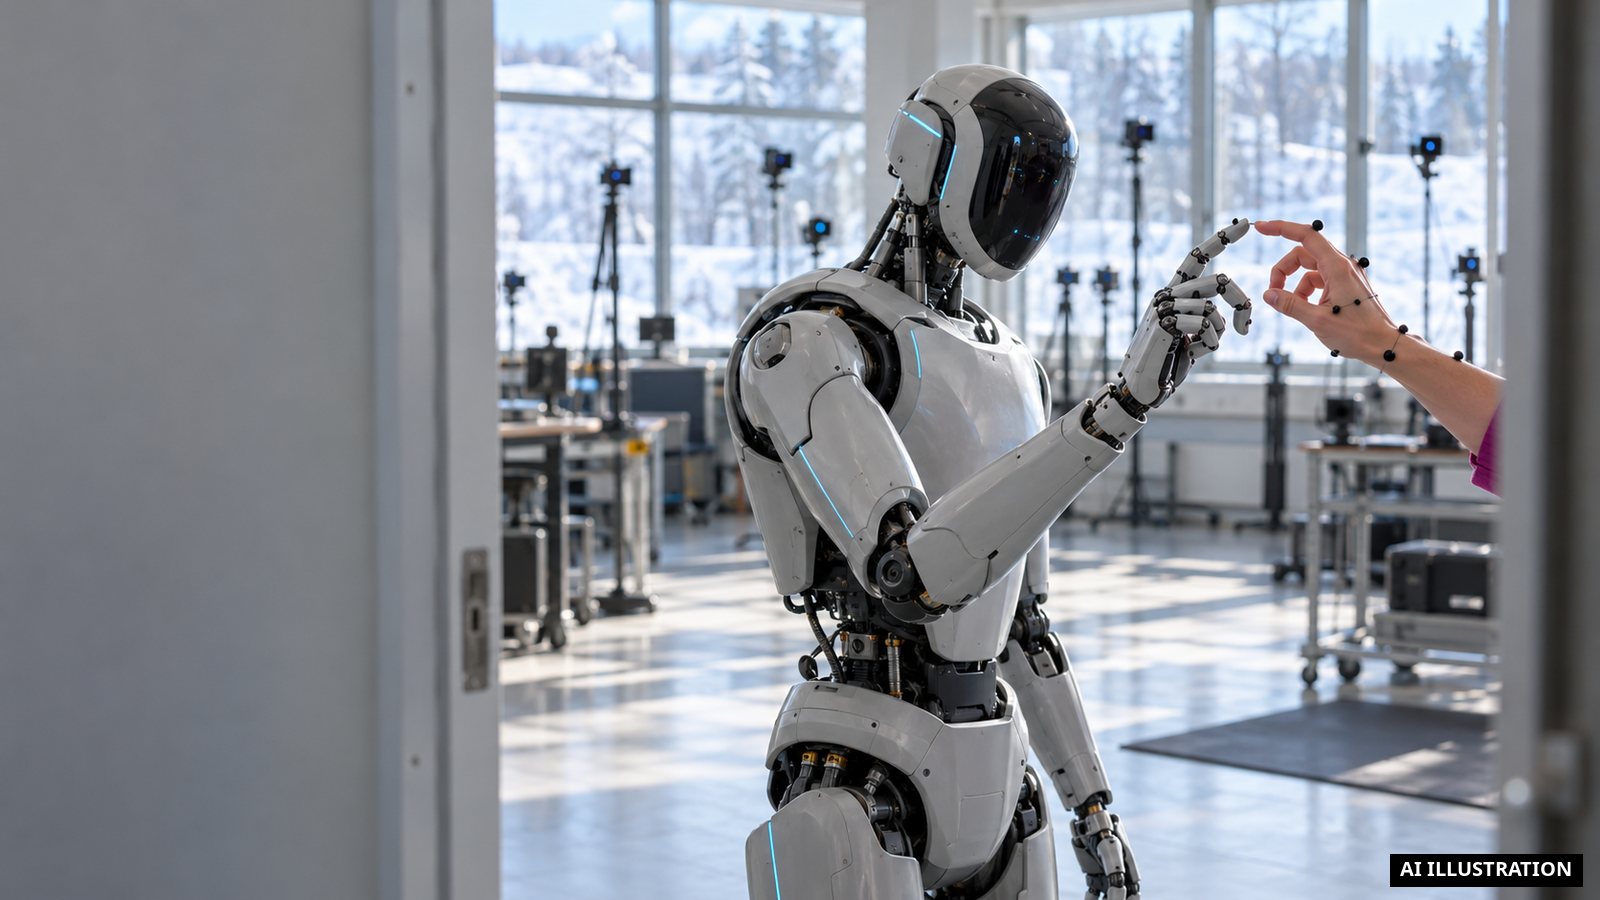
On 10 March, NEURA Robotics and the MIRMI of the Technische Universität München jointly announced the TUM RoboGym. The presentation is straightforward: the largest scientific centre in Europe dedicated to training Physical AI at the time of its announcement. But the internal setup says better than superlatives what it is about. The learning data is captured there by human trainers wearing MANUS gloves and an Xsens body motion capture system, then injected into the Neuraverse platform.
This is the literal admission of the bottleneck: we pay humans to hand-craft the missing raw material. Neuraverse is also designed as a hardware-agnostic collection and distribution system, intended to open up to industrial partners and startups, and the majority of the data generated at the RoboGym will be shared as open source with the robotics community. The human gesture, captured and redistributed, as a resource. The data is not a by-product of training: it is the product, and it takes a €17 million hall to produce it.
Answer No. 2: Synthesising it through computation
At GTC 2026, on 16 March, NVIDIA does the exact opposite operation — and owns it. Jensen Huang unveils GR00T N2 in advance, a robotic foundation model derived from internal research DreamZero, featuring a 'world action model' architecture, with general availability announced for late 2026. According to NVIDIA, robots executing it succeed at new tasks in unknown environments more than twice as often as competing vision-language-action models.
Around the model, a whole synthesis chain: the Physical AI Data Factory Blueprint, an open reference architecture for generating training data at large scale, built on the Cosmos world model and the OSMO orchestrator; Isaac Lab 3.0 in early access, a reinforcement learning engine based on the Newton 1.0 physics engine and optimised for DGX infrastructure. The Decoder summarises the manoeuvre without mercy: NVIDIA wants to 'transform the robotics data problem into a computation problem'.
The demonstration that condenses everything is Olaf. To train this robot, 100,000 virtual instances were simulated simultaneously in two days on a single NVIDIA RTX 4090 GPU, via the Kamino simulator — a proprietary tool from Disney Research, built on the Newton solver and accelerated by graphics card. There is the hard figure, exhumed under the folklore of three billion humanoids: not a 2060 horizon, but 100,000 instances in two days on a consumer-grade card. The day training a robot ceases to be a problem of arms and gloves and becomes a problem of graphics cards, the centre of gravity of the industry leaves the workshop for the data centre. And the consequence is clear: if data becomes computation, the one who sells computation owns the data by default.
Answer No. 3: Decreeing it
On 12 March, the National People’s Congress formally adopted the 15th Chinese Five-Year Plan (2026-2030). For the first time, embodied artificial intelligence is classified therein as an autonomous strategic industrial category, on the same level as quantum, brain-machine interfaces, and 6G; humanoid robots are among the eight designated national strategic industries, a status elevation compared to the 14th plan.
The detail that matters here is not the general ambition, but the list. The plan enumerates five axes for embodied AI, and two of them precisely name data as state infrastructure: coordination of training grounds and virtual-real fusion for collaborative training — that is, the first two answers, collection and synthesis, planned from the top. All backed by a state venture capital fund of 1,000 billion yuan (approximately $138 billion) dedicated to AI, robotics, and emerging technologies.
And for the data to exist, there must be bodies that produce it. In March, UBTech Robotics signed a strategic cooperation agreement with Siemens Digital Industries Software to bring the production of the Walker S2 to 10,000 units per year, integrating Siemens design, simulation, and planning software into the entire manufacturing cycle. Mass-producing the machines that, once deployed, will in turn generate the data: the loop closes at the scale of a State.
The 'geopolitical bifurcation' does not hold
The easy narrative of the week was that of a fracture: a European counterweight — the RoboGym explicitly positions itself against the forty Chinese collection centres and American initiatives — against rival blocs. The graph of the week dismantles this narrative.
The only real autonomy demonstrated, without a teleoperator, is at GTC: RealSense and LimX Dynamics achieve the world’s first demonstration of autonomous 3D navigation for a humanoid, combining RealSense depth cameras and NVIDIA’s cuVSLAM, the robot moving in spaces shared with humans without the slightest intervention from an operator. Yet this robot is Chinese — LimX is based in Shenzhen — and it was trained by reinforcement learning in NVIDIA Isaac Lab to reduce the sim-to-real gap.
The same week, NEURA (Europe), Figure AI (USA), Agility Robotics (USA) and AgiBot (China) all announce the adoption of the Isaac GR00T N models — while NVIDIA entrusts the Newton engine to the Linux Foundation and publishes it as open source under the Apache 2.0 licence, co-developed with Disney Research and Google DeepMind. The 'camps' may be fighting over the data by geography. But they are all training it on the same simulator, with the same foundation model, on the same physics engine. The fracture is in the collection, not in the tool: at the stack level, there are not two blocs, there is one supplier.
One layer lower
This thread descends the stack layer by layer, week after week. In December, the demo was the product; at CES in January, teleoperation became a data business; in February, the body revealed itself as consumable, the value resided in the brain; on 9 March, the question was: who owns the brain? This week descends one step further, under the brain: who owns the data factory that feeds it? The object is new — training data and its mode of production — and it is attested the same week by a physical centre (the RoboGym), a synthesis stack (the Data Factory and Olaf) and a state plan (the 15th Plan).
So do not ask which robot walked best this week. Ask where its training data comes from. The three answers — picking it up by hand, simulating it, decreeing it — draw the true map of forces. And while the three are busy, NVIDIA is working to ensure that only one question remains to be asked: how many GPUs?